Gemini 4 Carbon vs Fable 5.2 vs Opus 5.5 vs GPT-6.1 Sol: Blind Test
Same prompt, 4 AI models: a Blender Lamborghini, a driving game, 2 Leonardo machines. AI judges picked Carbon, I picked Fable. Play all 16 builds.
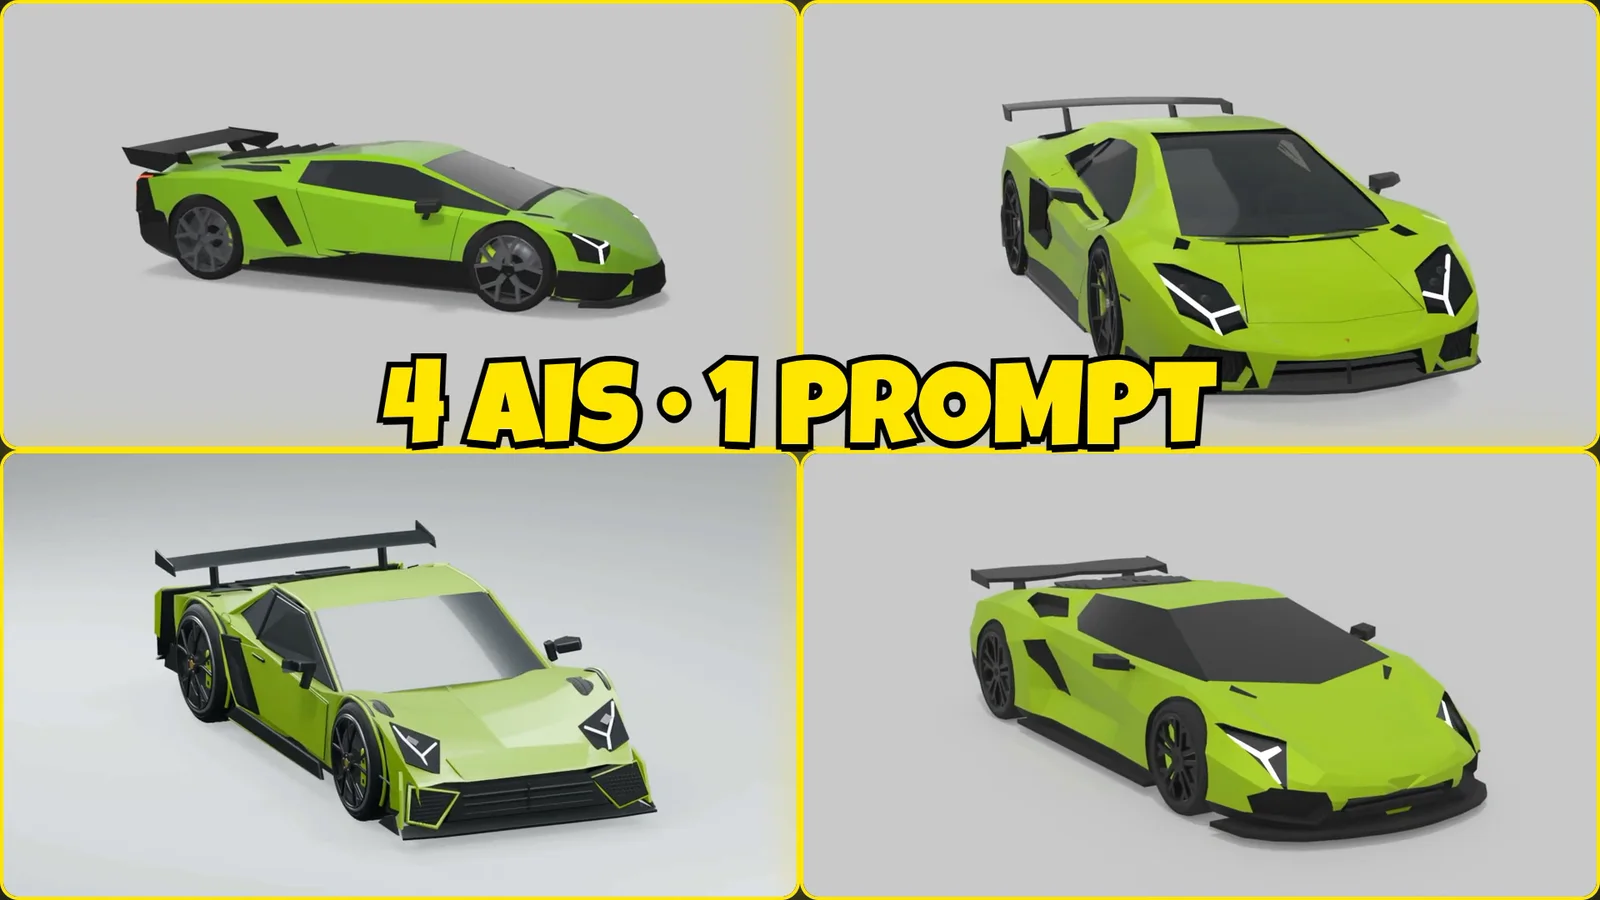
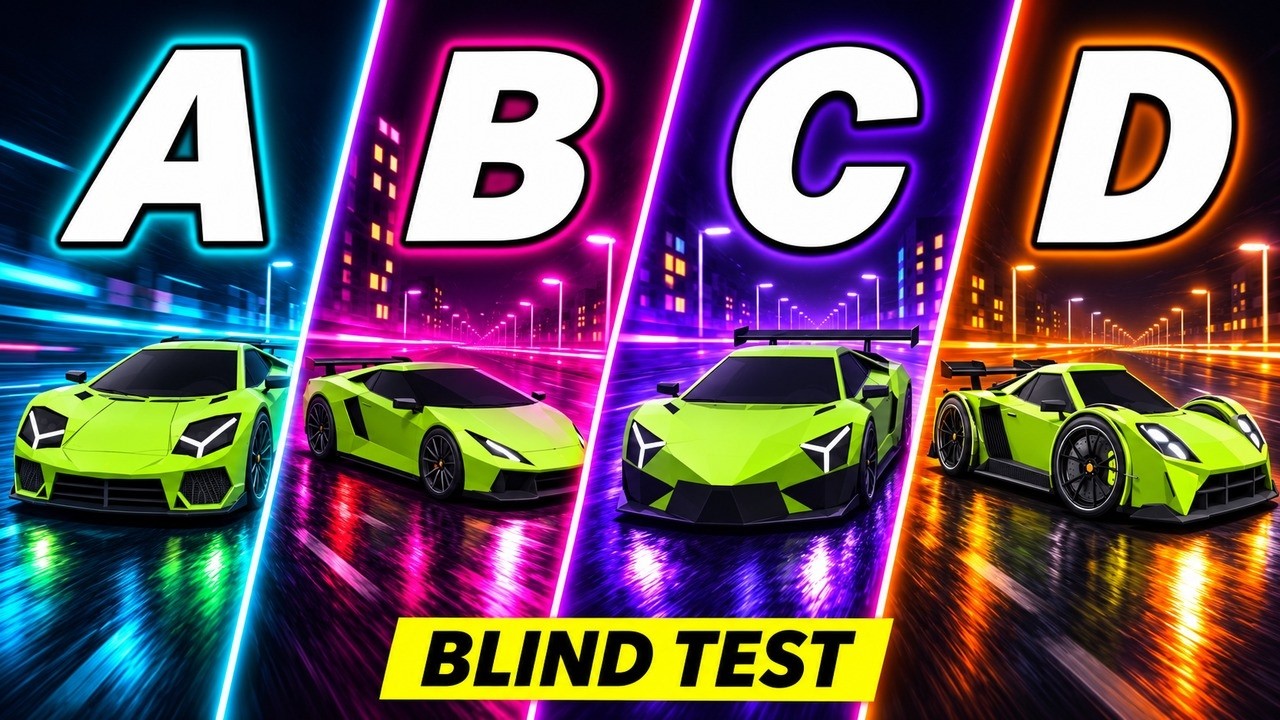
Gemini 4 Carbon, Claude Fable 5.2, Claude Opus 5.5 and GPT-6.1 Sol each got the same prompt and the same pictures in November 2026: build a Lamborghini-style car in Blender, build a driving game around it, and rebuild two Leonardo da Vinci machines in 3D. Three AI judges scored the results blind and put Gemini 4 Carbon first on every judged test. I voted blind too and put Claude Fable 5.2 first on every test. Fable also cost the most: $41.85 at API list price for the four tests, against $2.11 for GPT-6.1 Sol. All 16 builds are playable below.
Play them yourself: kartit.net/games/ai-battle (four driving games, four 3D cars, eight Leonardo animations).
Key facts (quick answer)
| Fact | Result |
|---|---|
| Models | Gemini 4 Carbon, Claude Fable 5.2, Claude Opus 5.5, GPT-6.1 Sol |
| Tools | Antigravity (Carbon), Claude Code (Fable, Opus), Codex (Sol), all at high effort |
| Tests | Blender Lamborghini, browser driving game, Leonardo’s aerial screw, Leonardo’s gear hoist |
| AI jury winner (blind, 3 judges) | Gemini 4 Carbon on all 3 judged tests |
| My winner (blind) | Claude Fable 5.2 on all 3 judged tests |
| Fastest | GPT-6.1 Sol, 39.7 min for 4 tests |
| Cheapest | GPT-6.1 Sol, $2.11 at API list price |
| Most expensive | Claude Fable 5.2, $41.85 at API list price |
| Carbon’s bill | $10.17 on my Gemini API key |
| Try the builds | kartit.net/games/ai-battle |
TL;DR
- Same prompt, same 5 pictures, one try each, high effort, four tests: a Blender car, a game, two Leonardo machines.
- AI jury (Gemini 4 Argon, Claude Opus 5.5, GPT-6.1 Sol, blind): Gemini 4 Carbon first three times, 8.03, 8.63 and 8.20 out of 10.
- My blind vote: Claude Fable 5.2 first three times, 8, 9 and 10 out of 10.
- Speed: GPT-6.1 Sol finished all four tests in 39.7 min; Fable took 133.1 min.
- Cost: Sol $2.11, Carbon $10.17, Opus $16.77, Fable $41.85. Fable cost about 20 times Sol.
- Everything is playable on a computer or a phone.
What exactly did the four AI models build?
Each test was one prompt, typed once, with the same reference pictures for everyone:
- The Lamborghini. Five views of a lime-green supercar (front, both sides, back, top). “Build this car as a 3D model in Blender, from code”, with renders and an 8-second turntable.
- The driving game. “Your own 3D car is in the current folder: build a small driving game in the browser around this car”, with a track, speed, boost, an intro camera move and touch buttons for phones.
- Leonardo’s aerial screw. His sketch from around 1489, rebuilt in 3D, then taken apart one element at a time with a label on each part, held exploded, and put back together.
- Leonardo’s gear hoist. A mechanism he drew already exploded: pegged wheels, lantern gears, a winch, a rope and a weight. Same task, harder.
Who won the blind test?
Entries were shown as letters in a random order, with the model names hidden, both to the AI judges and to me. The AI jury score is the mean of three judges.
| Test | Gemini 4 Carbon | Claude Fable 5.2 | Claude Opus 5.5 | GPT-6.1 Sol |
|---|---|---|---|---|
| Lamborghini, AI jury | 8.03 | 6.43 | 5.60 | 6.37 |
| Lamborghini, my vote | 6 | 8 | 5 | 4 |
| Aerial screw, AI jury | 8.63 | 7.97 | 8.07 | 7.03 |
| Aerial screw, my vote | 8 | 9 | 7 | 6 |
| Gear hoist, AI jury | 8.20 | 7.97 | 7.03 | 6.80 |
| Gear hoist, my vote | 7 | 10 | 8 | 6 |
| Driving game | not judged | not judged | not judged | not judged |
The driving game was not scored by anyone. You are the jury on that one: play the four games.
How much did each model cost, and how long did it take?
Times and token counts come from each tool’s own logs; the Claude numbers were checked with ccusage. Prices are the vendors’ list prices on 11 November 2026: Gemini 4 Carbon $2 / $10 per million input / output tokens, Claude Fable 5.2 $8 / $40, Claude Opus 5.5 $4 / $20, GPT-6.1 Sol $2 / $10.
| Test | Gemini 4 Carbon | Claude Fable 5.2 | Claude Opus 5.5 | GPT-6.1 Sol |
|---|---|---|---|---|
| Lamborghini | 43.7 min, $4.37 | 29.3 min, $9.90 | 27.6 min, $6.03 | 17.9 min, $0.80 |
| Driving game | 21.3 min, $1.92 | 26.2 min, $8.45 | 17.0 min, $3.93 | 8.5 min, $0.50 |
| Aerial screw | 28.2 min, $1.91 | 27.3 min, $9.73 | 14.2 min, $3.14 | 5.5 min, $0.32 |
| Gear hoist | 29.1 min, $1.97 | 50.3 min, $13.77 | 14.7 min, $3.67 | 7.8 min, $0.49 |
| All four | 122.3 min, $10.17 | 133.1 min, $41.85 | 73.5 min, $16.77 | 39.7 min, $2.11 |
What “API list price” means here. Fable, Opus and Sol ran on my Claude and ChatGPT subscriptions, so I paid nothing extra for these runs. Their dollar figures are what the same tokens would cost if you called the model through its API. Gemini 4 Carbon ran on my own Gemini API key, so its figure is real money billed to me. Google’s page says Carbon’s price doubles to $4 / $20 from 1 December 2026, which would double that bill.
Why did the AI judges and I disagree?
The judges wrote a reason for every score, and most of them are about faithfulness: the right parts, labels that match, proportions close to the reference, nothing cropped. Carbon’s builds scored highest on that. I voted on my overall impression of each build, without knowing who made it, and Fable came out on top for me three times. My only written notes were on the hoist: Opus “very good, winch rope not perfectly rotating” and Fable “this is very good actually too”. Both views are fair, which is why the video asks you to score the builds yourself before the reveal.
Play them yourself
Everything is unedited AI output, live in your browser:
- Driving games (keyboard or touch): Gemini 4 Carbon, Claude Fable 5.2, Claude Opus 5.5, GPT-6.1 Sol
- The 3D cars (drag to spin): all four in one viewer
- Leonardo’s aerial screw: Carbon, Fable, Opus, Sol
- Leonardo’s gear hoist: Carbon, Fable, Opus, Sol
Caveats
- One run per model per test. A second try could land differently; this is a snapshot, not a benchmark.
- The judges are AI models from the same labs. Gemini 4 Argon, Claude Opus 5.5 and GPT-6.1 Sol judged blind, and I used three of them so no single lab decides.
- Costs are for the runs shown. Each number is the time and cost of the run you see in the video and can play on this site.
- Subscription dollars are equivalents, not bills. Only Carbon’s figure is money actually charged.
- The driving games were not scored by the jury or by me.
My take
If you want the result that matches the brief most completely, the AI judges say Gemini 4 Carbon, and at $10.17 for four big builds it is good value until its price doubles in December. If you want the build you would rather show someone, I picked Claude Fable 5.2 every time, blind, but it took the longest and cost the most. GPT-6.1 Sol is the value pick: under 40 minutes and about two dollars for all four. Play them and decide for yourself.
Sources
- My test logs (tool logs for time and tokens, ccusage for the Claude runs), November 2026.
- Vendor pricing pages, read on 11 November 2026: Gemini API pricing, Claude pricing, OpenAI API pricing.
- Leonardo da Vinci’s aerial screw (Manuscript B, about 1489) and gear hoist sketches (Codex Atlanticus), used as the reference images.
Independent test by Anass Kartit. Not affiliated with Google, Anthropic or OpenAI. Video made with ZArchitect.
Newsletter
Get the next post and game in your inbox
One email when I publish something new: measured write-ups on AI, local models and cloud, plus games like NEON RUN.